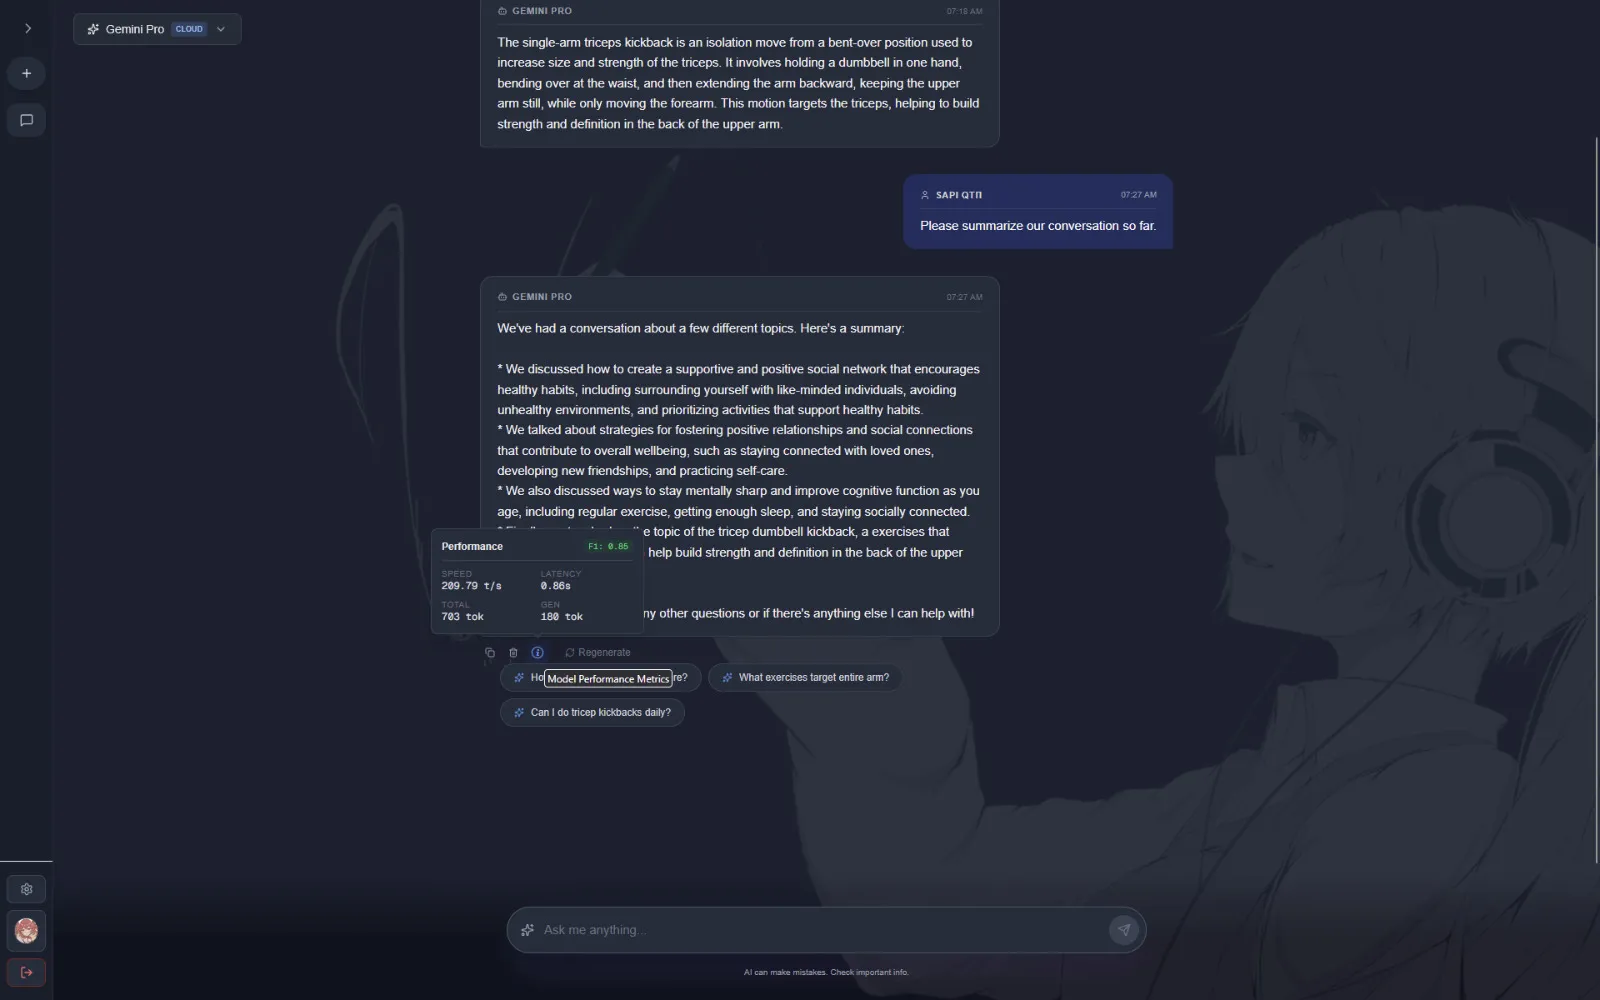
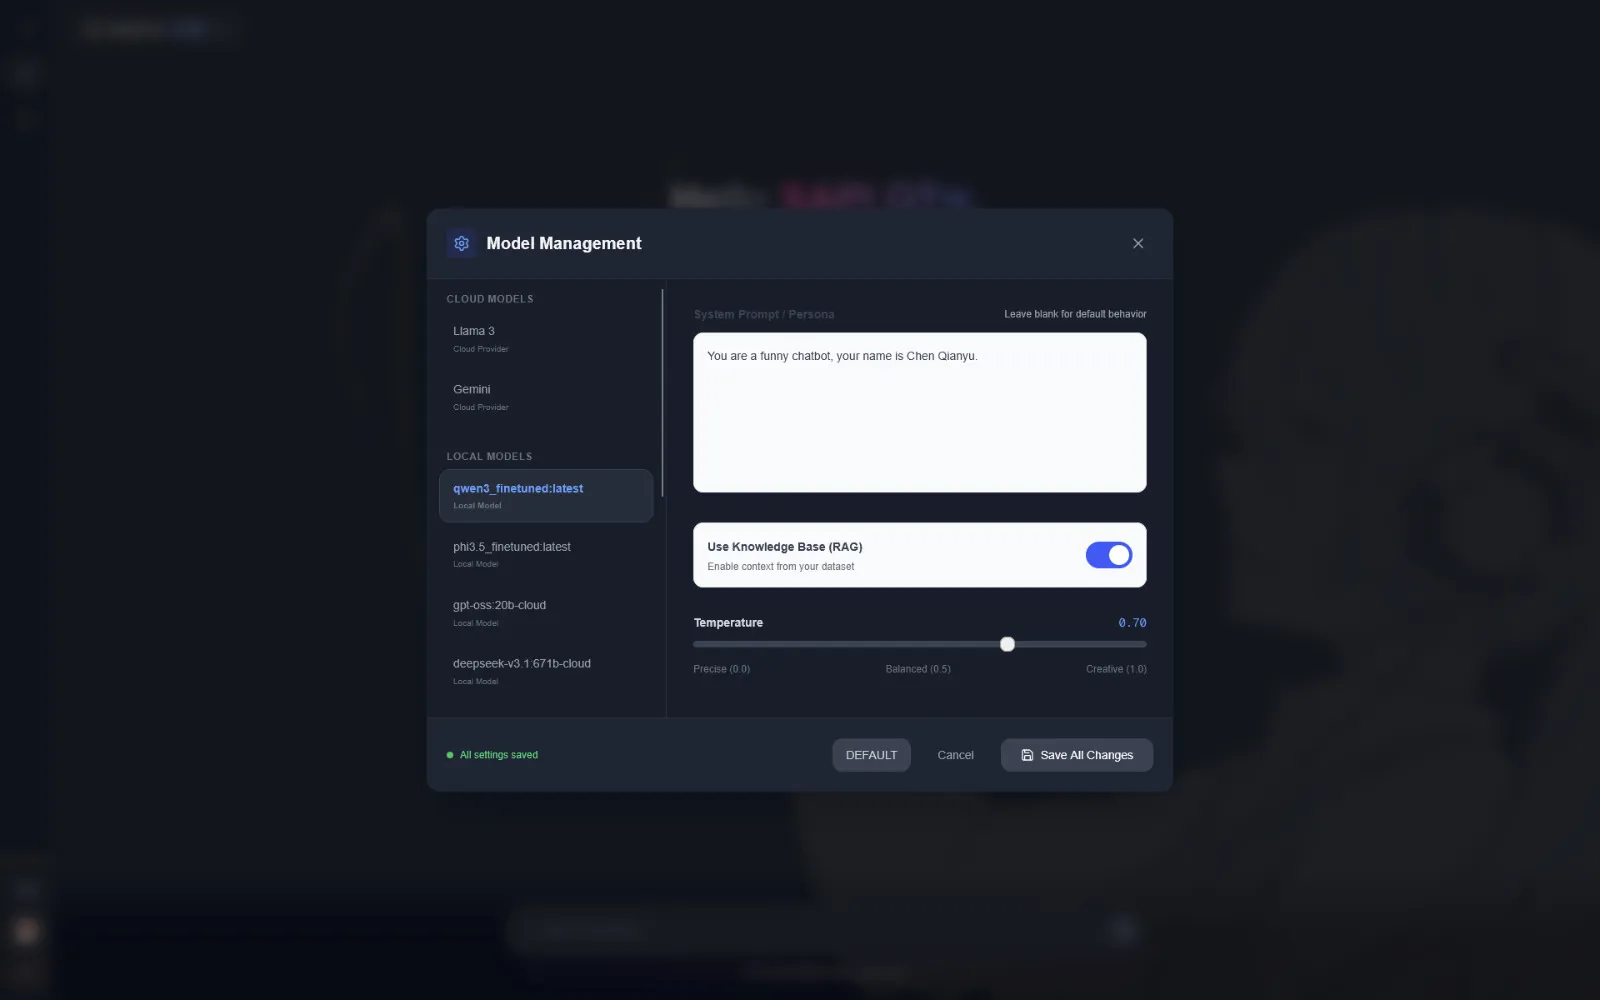
NLP Hybrid Chatbot (RAG)
Ultra-fast Document Q&A powered by Llama 3 and FAISS Vector Search

Overview
A hybrid conversational AI assistant combining semantic vector search with large language models through Retrieval-Augmented Generation (RAG). By integrating FAISS vector indices with Groq's high-speed inference engine, the system delivers millisecond response times on complex document queries.
Introduction & Problem
Standard LLMs suffer from hallucination and lack up-to-date or domain-specific context. This hybrid RAG architecture grounds language models on curated knowledge bases, ensuring responses are verifiable, hallucination-resistant, and instantly sourced from reference materials.
Tools & Technologies
Ultra-low latency LLM inference producing natural, detailed answers.
High-dimensional vector indexing for sub-second semantic retrieval.
Document chunking, vector embedding generation, and prompt engineering.
Key Features & Architecture
Context-Grounded Retrieval
Extracts top-k semantic chunks from uploaded documents to provide accurate answers.
Sub-Second Groq Generation
Leverages specialized LPU hardware for unprecedented token generation speeds.
Source Attribution
Cites document references to prevent hallucinations and establish trust.
Results & Impact
Inference Engine
Groq LPU
Sub-second token throughput
Vector Search
FAISS
Dense cosine similarity retrieval
LLM
Llama 3 8B/70B
High reasoning capability
Project Gallery